Behavioral Signals
API for speech emotion, behavior, speaker attributes and voice deepfake detection, batch or live.
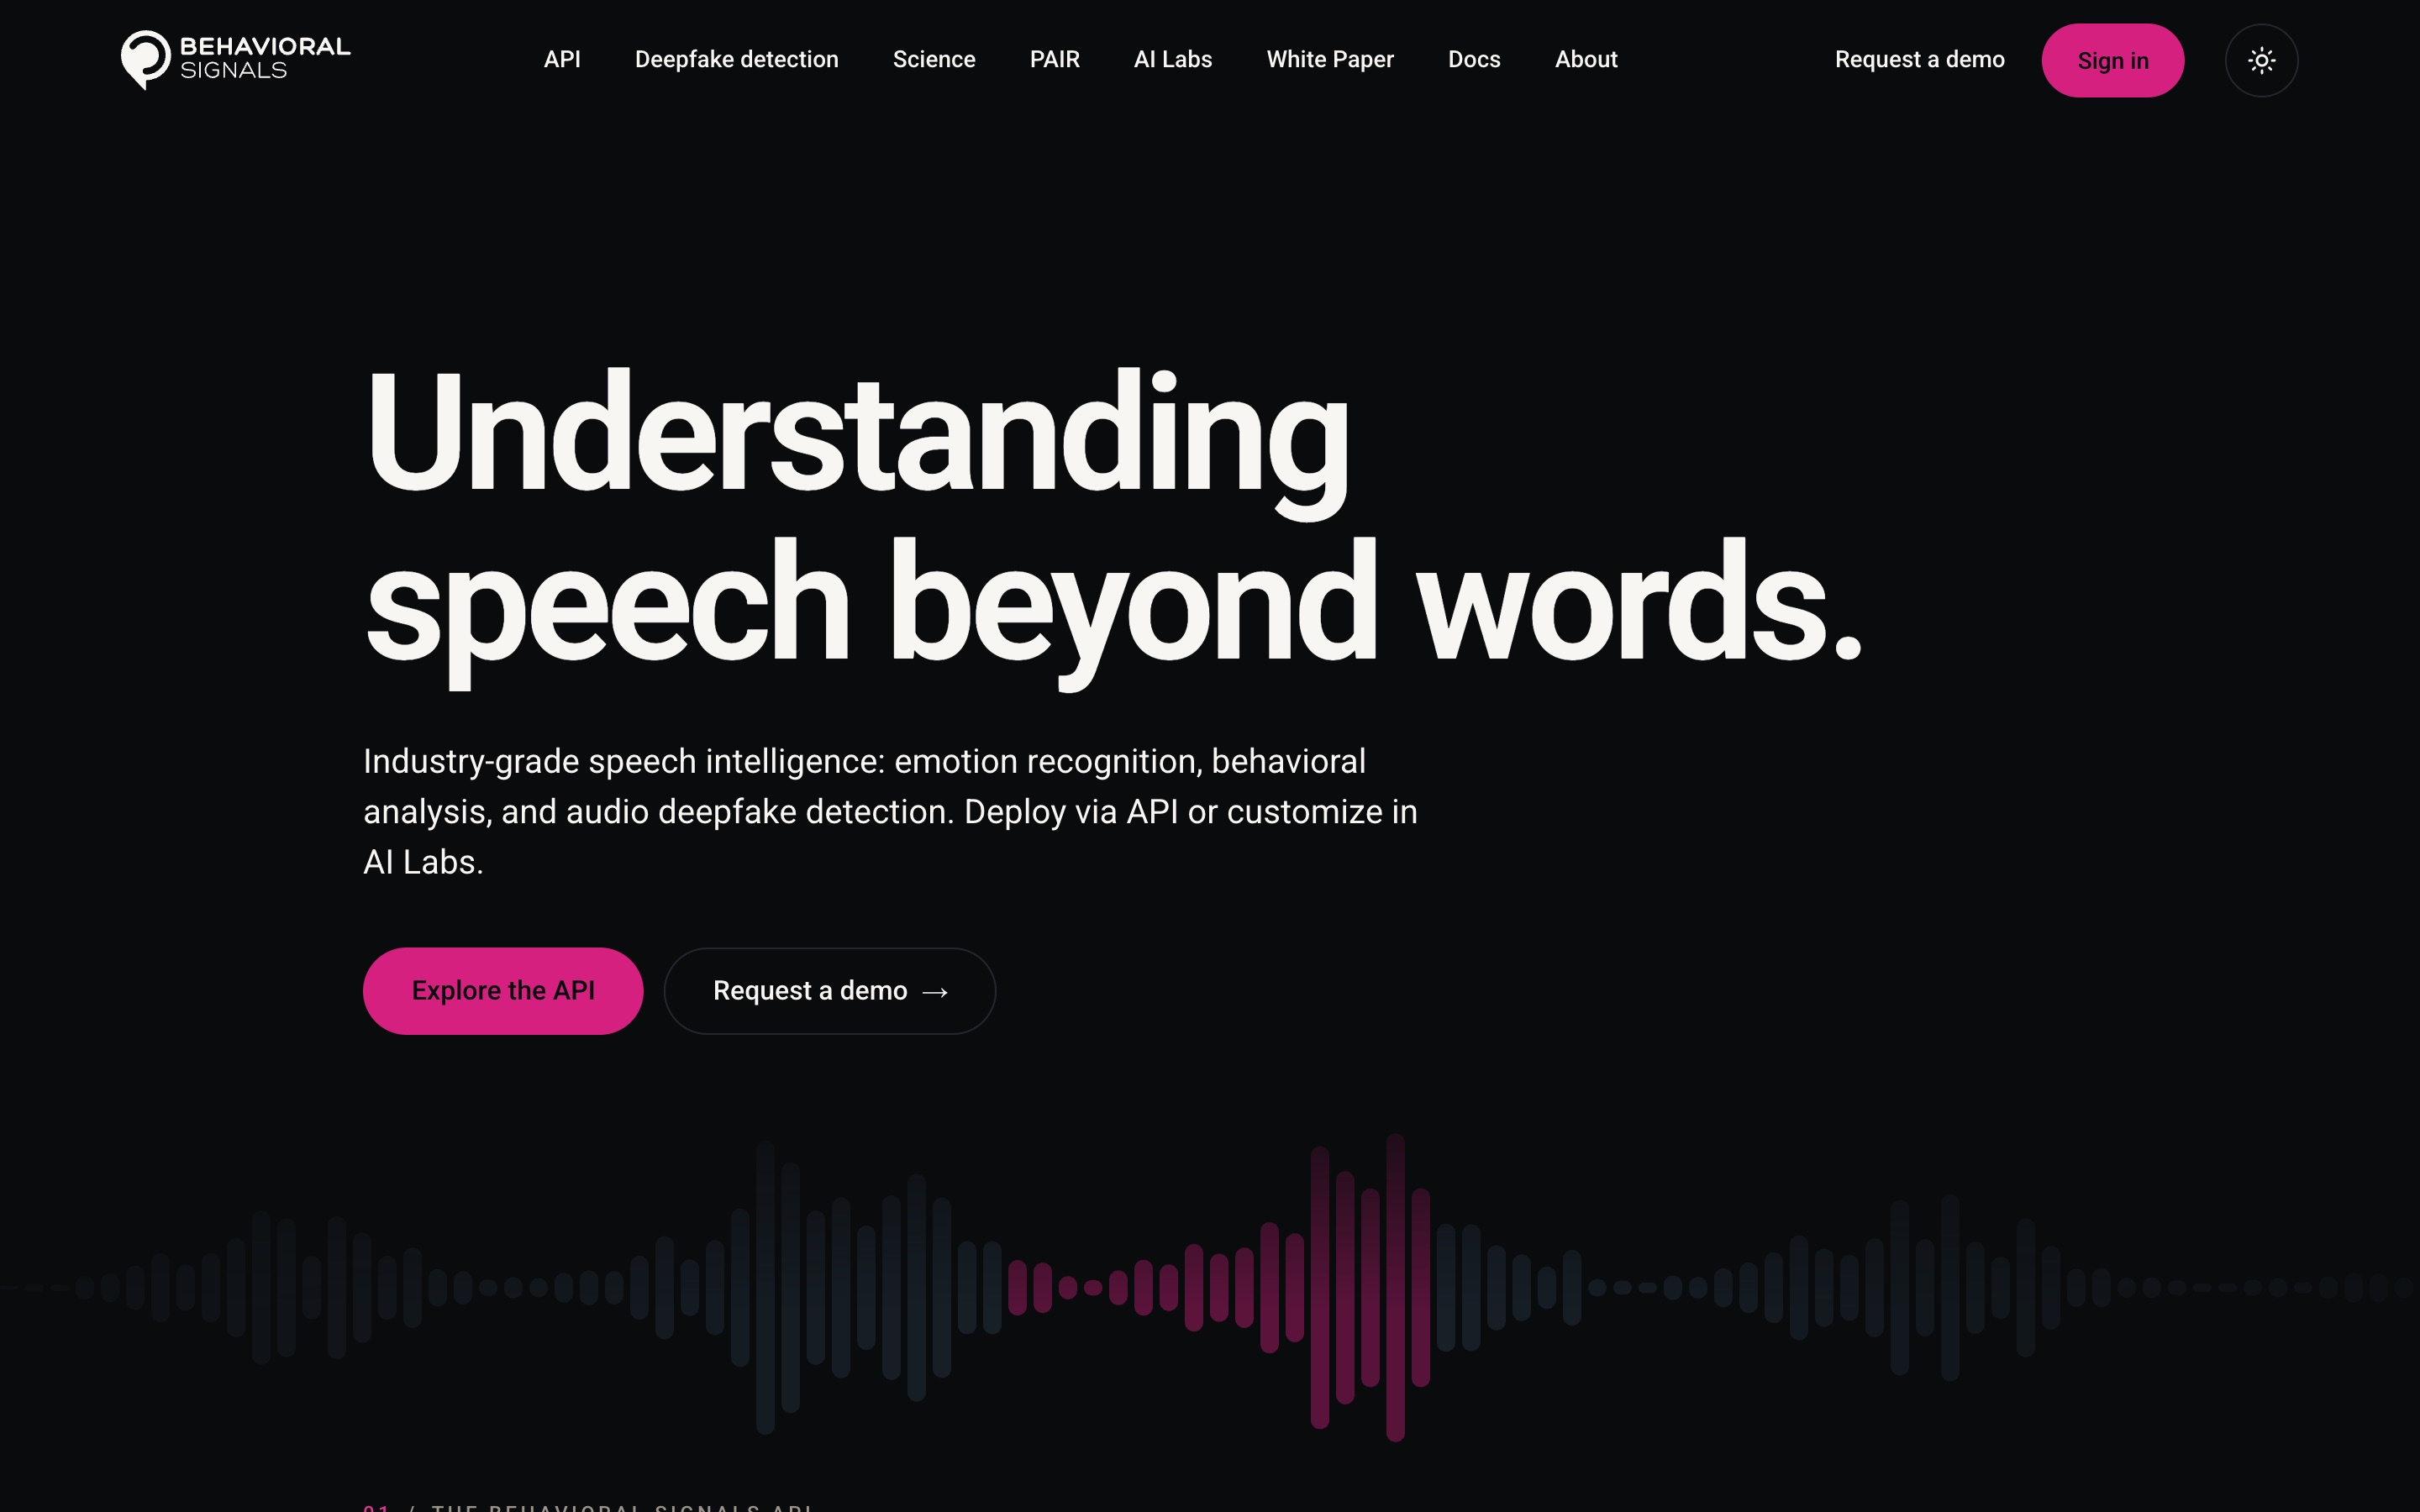
About Behavioral Signals
Behavioral Signals: Speech Emotion, Behavior and Deepfake Detection API
Behavioral Signals offers a speech intelligence API that analyzes how something is said, not only what is said, returning emotion, behavior, speaker attribute and voice deepfake estimates for each utterance. Developers can send recorded audio or live streams, and the same models also run in customer-hosted deployments and at the edge.
Key Features
Emotion and Behavior Signals: Per utterance or two-second segment, the API returns emotion, positivity, strength, speaking rate, hesitation, engagement and intensity, plus estimated gender and age range, each with class probabilities.
Deepfake Speech Detection: Returns bonafide or spoofed probabilities per utterance, combining acoustic artifacts with prosody, speaking style and emotion. It works across languages and on live calls.
Real-Time Streaming: A gRPC streaming API and Python SDK return results during the call; recorded audio goes through a REST batch API.
Transcripts Included: Batch results also carry the transcript, speakers and language per utterance at no extra charge.
Focus: Flags moments matching labels you choose, such as stress or low confidence, at a chosen sensitivity, without re-uploading audio.
Language Coverage: The models read how something is said, not the words, and perform best in their 11 training languages, including English, Arabic, Chinese, Hindi and Spanish.
Pipecat Integration: The open-source pipecat-behavioralsignals package adds a voice reading to most user turns in a Pipecat agent, right after speech-to-text.
PAIR and AI Labs: PAIR routes contact-center calls by predicted customer and agent compatibility, and AI Labs builds custom models for cloud, on-premises and edge.
Use Cases
Voice agents that adjust their replies when a caller sounds hesitant, rushed or withdrawn.
Contact centers screening calls for signs of AI-generated speech as part of a wider security review.
Conversation analytics and call routing based on how customers and agents speak.
Custom speech models for areas such as stress detection, cognitive impairment screening and media content analysis.
Pricing
Free start: 30 free minutes, no credit card required.
Behavioral signals: $0.10 per minute batch, $0.15 per minute streaming.
Deepfake audio: $0.25 per minute batch, $0.50 per minute streaming.
On-premises deployments: priced on request.
Getting Started
Website: https://behavioralsignals.com
Documentation: https://docs.behavioralsignals.com
Pipecat integration: https://behavioralsignals.com/pipecat
Behavioral Signals gives developers emotion, behavior and synthetic speech signals read from the voice itself, ready to feed into voice agents, contact-center tools and analytics.
Shrikanth Narayanan
Co-founder & Chief Scientist at Behavioral Signals


