Baseten
AI inference platform for open and custom models, including a co-located voice agent stack.
About Baseten
Baseten: Inference Platform for Open and Custom Models
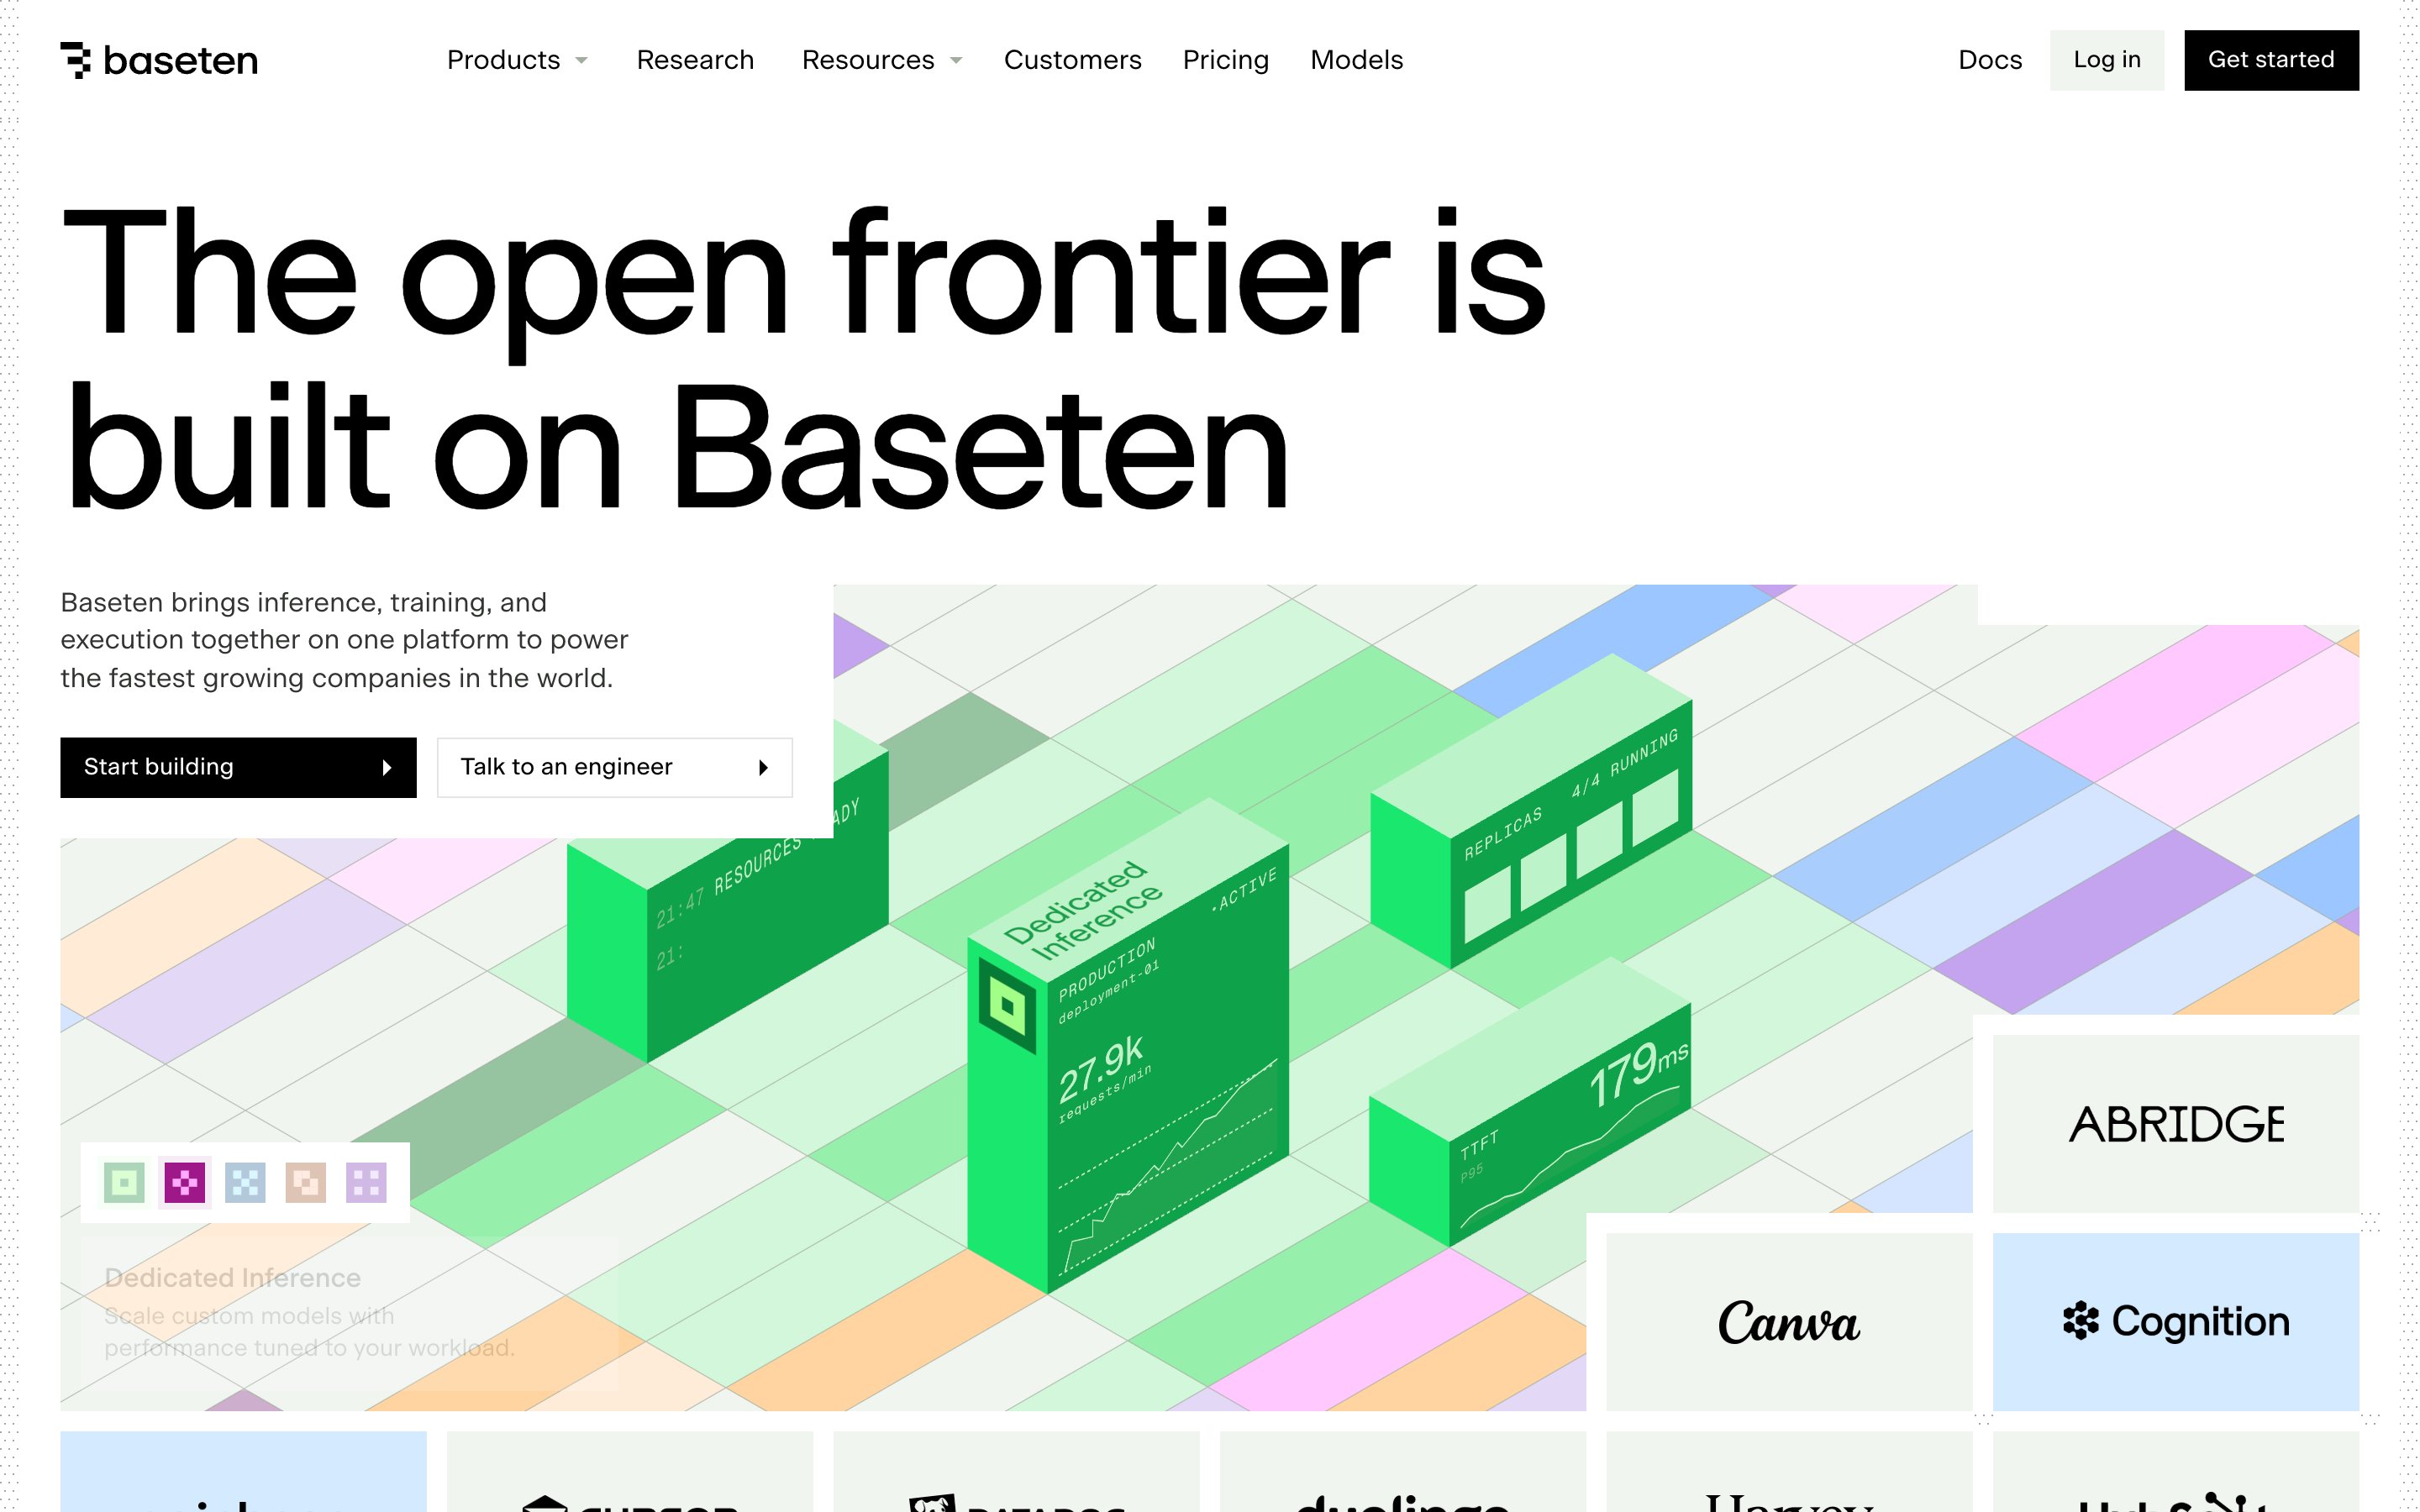
Baseten is an AI inference platform that runs open-weight and custom models on dedicated GPUs or through per-token Model APIs. For voice, its Voice Agent Stack co-locates speech-to-text, the LLM, text-to-speech and the orchestrator in one region to cut network round trips. The platform also covers training and sandboxes for agents.
Key Features
Dedicated Inference: Deploy custom and fine-tuned models on dedicated GPUs, with performance tuned to the workload and autoscaling per deployment.
Model APIs: Per-token APIs for open-weight frontier models, including GLM, DeepSeek, Kimi and NVIDIA Nemotron families.
Voice Agent Stack: Runs the speech-to-text, LLM and text-to-speech models and the orchestrator in the same cloud region, with per-component autoscaling and cross-cloud failover (private preview).
Realtime Voice: A reference voice agent API on open-weight models (Qwen3-ASR, Gemma-4-31B, Qwen3-TTS) with a custom Pipecat-based orchestrator, matching the core OpenAI Realtime protocol (private preview).
Talker and thinker delegation: A fast co-located model keeps the conversation going while a stronger model handles reasoning, search and tool calls in the background.
Training: Fine-tune or post-train models on your own data, for example speech-to-text on domain vocabulary, with your own code or the Loops SDK.
Multi-cloud capacity: Capacity across 20+ cloud providers, with failover and a stated 99.99% uptime.
Security and compliance: SOC 2 Type II, HIPAA support with a BAA, and GDPR, according to the Baseten security page.
Use Cases
Voice agents: Teams that want to own and optimize their speech and language models instead of calling hosted speech-to-speech APIs.
Speech models in production: Serving low-latency transcription and text-to-speech models at scale; Baseten lists Wispr Flow, Rime and Speechify as voice customers.
Custom models: Companies serving fine-tuned LLMs or domain speech models with their own data.
Migration from hosted APIs: Moving existing OpenAI Realtime-style agents onto open-weight models with minimal code changes, per Baseten.
Pricing
Usage-based, with no contract required. Dedicated GPUs are billed per minute (for example about $6.50 an hour for an H100 and $9.98 for a B200), Model APIs per million tokens. Volume discounts and reserved capacity are sold on request. Voice Agent Stack and Realtime Voice are in private preview, with no public price list.
Getting Started
Website: https://www.baseten.co
Documentation: https://docs.baseten.co
Realtime Voice waitlist: https://www.baseten.co/talk-to-us/realtime-voice-private-preview/
Baseten gives teams one platform to serve, train and scale their own models, including the speech and language models behind production voice agents.