
Allmodels
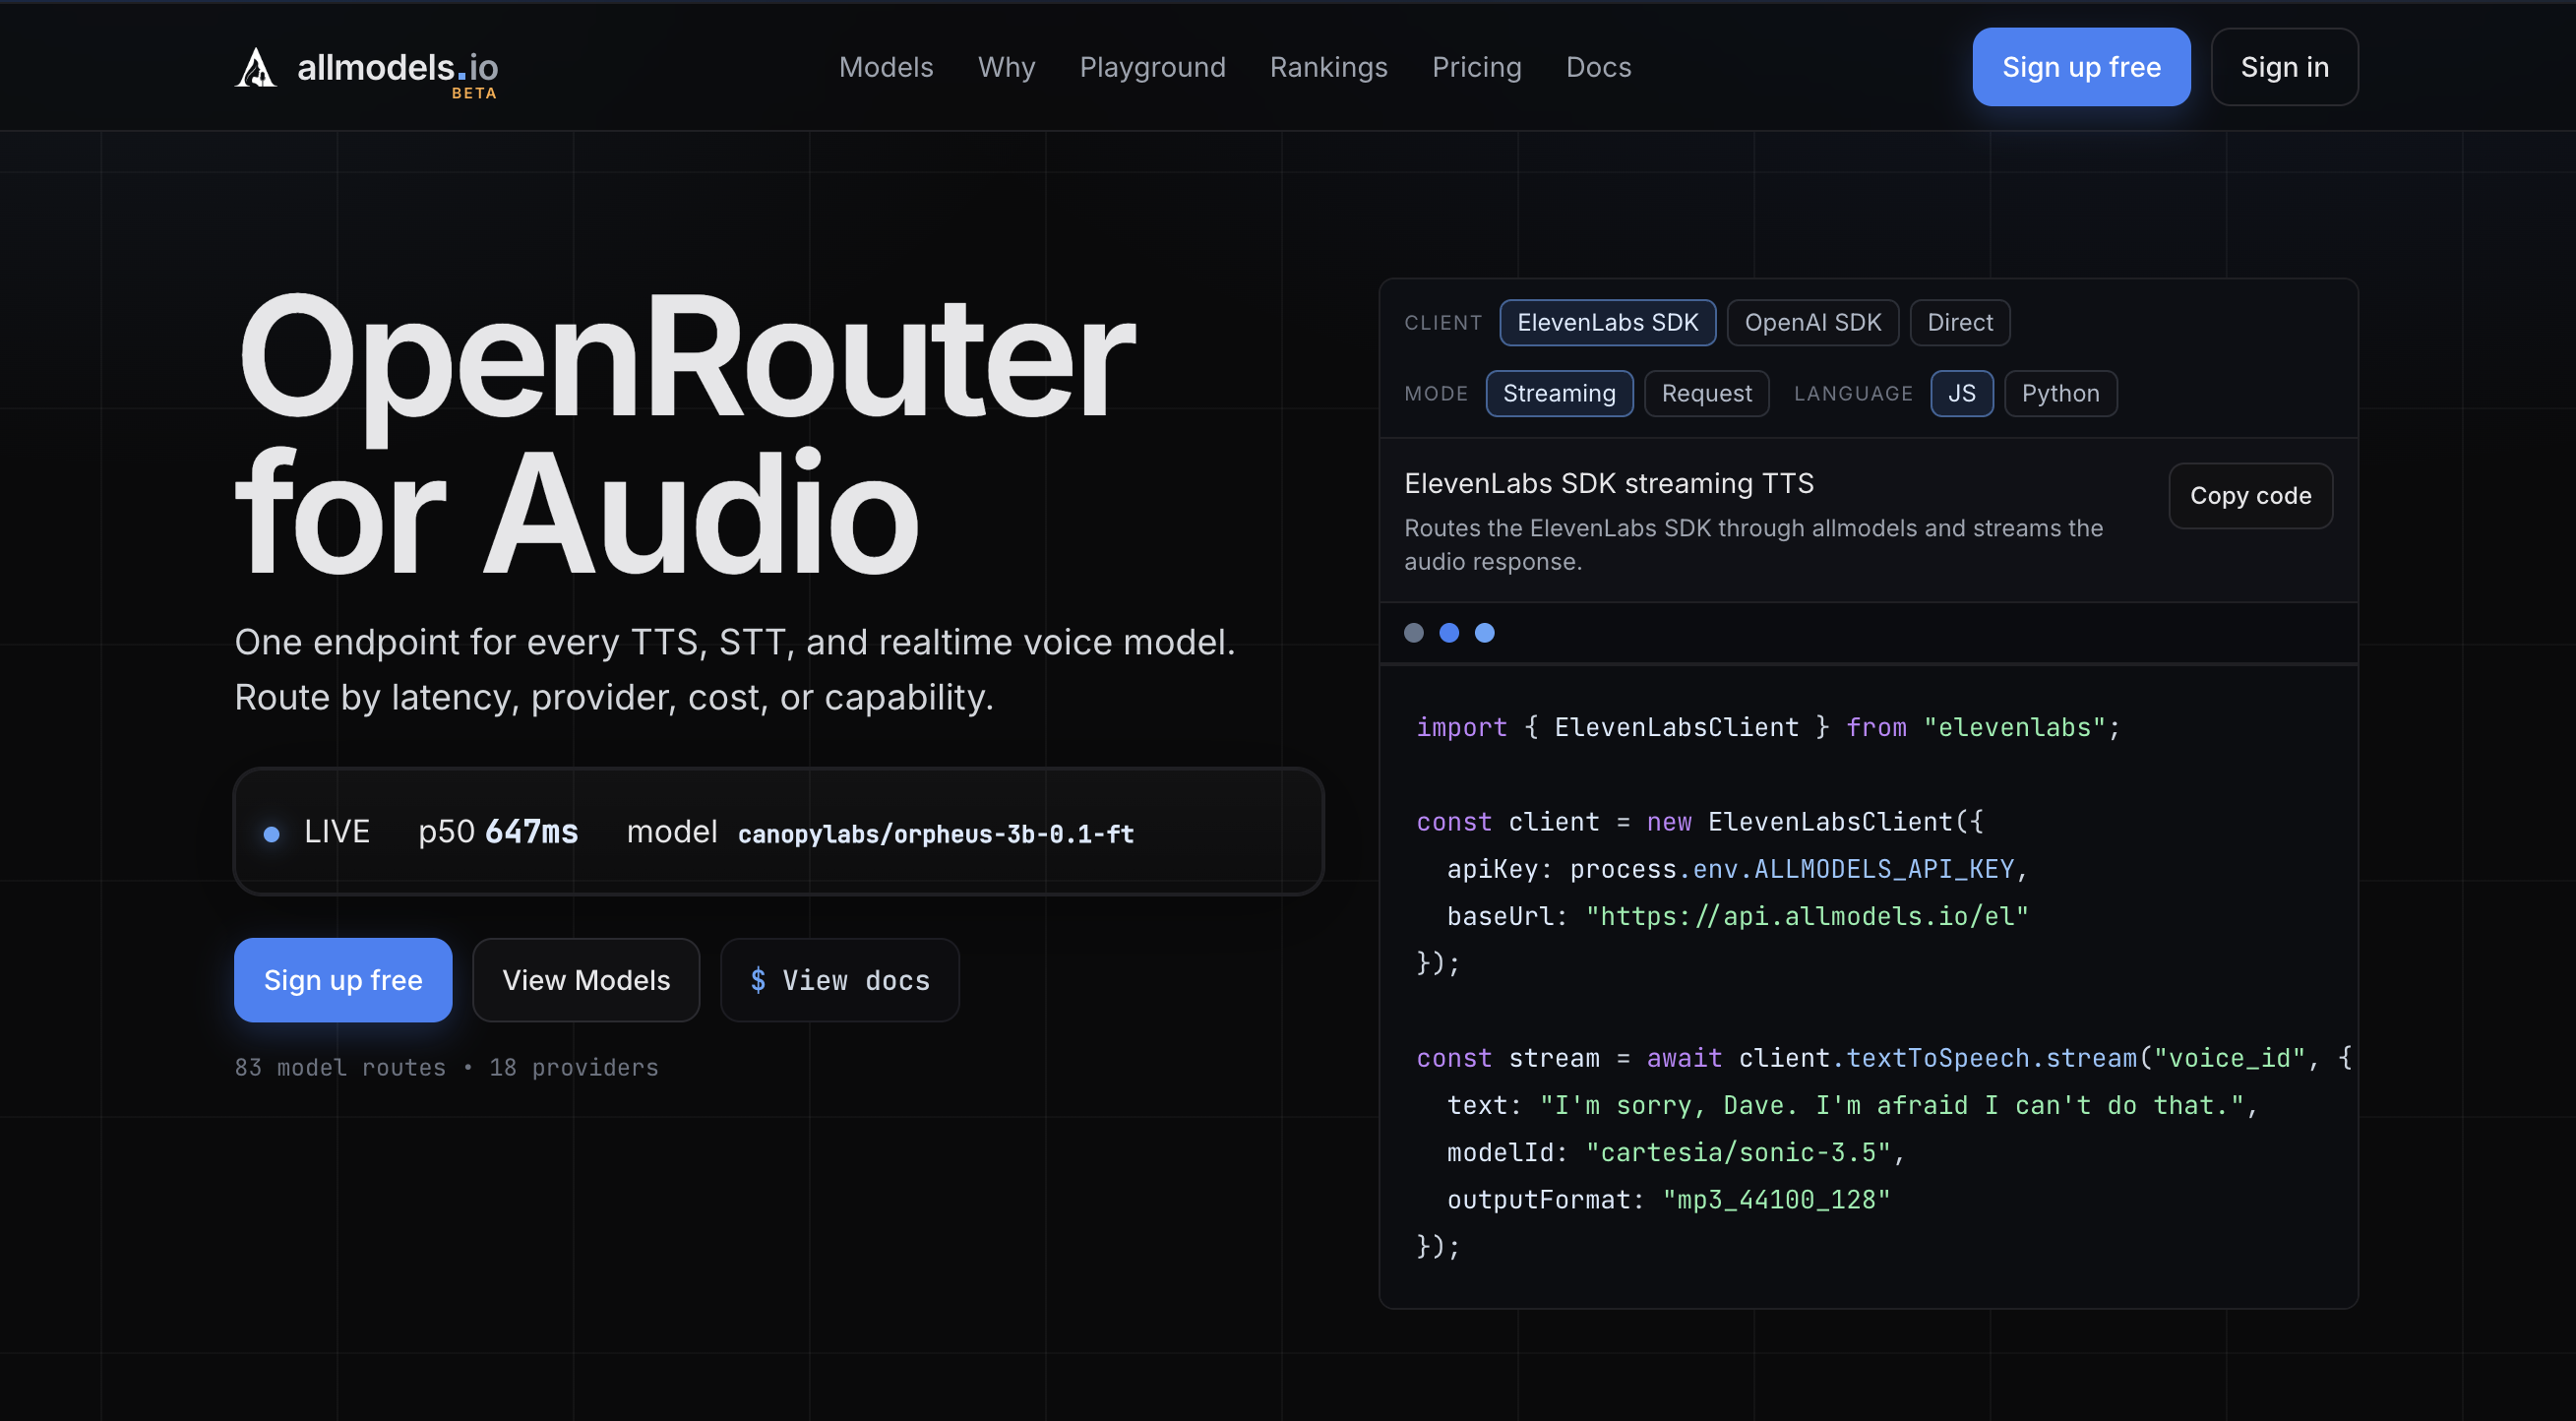
Unified API aggregating speech, transcription, and realtime audio models seamlessly.
About Allmodels
AllModels: One API for Every Voice Model
AllModels provides a unified API for voice technology, allowing developers to access and integrate multiple text-to-speech (TTS), speech-to-text (STT), and real-time voice models from various providers, all through a single endpoint. Built for voice agents requiring low latency and high flexibility, AllModels simplifies the integration and management of diverse and advanced audio models.
Key Features
Unified Endpoint: One API covers TTS, STT, and voice models from multiple providers, removing the need to integrate separate APIs.
Model Routing: Route requests by latency, cost, provider, or specific model capabilities for optimal performance.
Voice Portability: Allow users to retain voice consistency when switching providers; transfer a familiar voice between providers with ease.
MCP Server Integration: Manage account access, usage, and guardrails across clients like Claude, Cursor, and VS Code via secure OAuth sign-in.
Fast Response Times: Router latency under 30ms, with support for real-time audio needs.
Provider Diversity: Access 80 model routes spanning 18 different audio technology providers.
No API Key Exposure: Manage connections securely through dashboard settings, ensuring API keys are not embedded in clients.
Use Cases
Developers building voice agents or assistants needing seamless speech model integration.
Applications that require switching between speech models for latency, quality, or cost optimization.
Projects needing to maintain consistent voice output across different providers for a uniform user experience.
Teams wanting to manage and monitor model usage and API access from multiple development environments securely.
Getting Started
Website: https://allmodels.io
Documentation: https://allmodels.io/docs
MCP Server: https://allmodels.io/docs/mcp
AllModels empowers developers and teams to rapidly integrate, manage, and switch between cutting-edge voice models, enabling frictionless deployment of advanced voice applications while maintaining consistent quality, flexibility, and security.


