Reson8, the Amsterdam speech recognition company, has released Rumble-2-Flash as open weights under the Apache 2.0 license. The 0.5B-parameter speech-to-text model transcribes pre-recorded audio in more than 40 languages and is available on Hugging Face from November 18. It is small enough to run on a phone, a laptop or an on-prem server. Reson8 launched the hosted version of Rumble-2-Flash on November 3.
Model: Rumble-2-Flash open weights, 0.5B parameters
License: Apache 2.0, free download on Hugging Face
Languages: 40+, from Dutch, German and Swedish to Welsh, Basque and Maltese (full list)
Mode: pre-recorded audio (calls, lectures, voice notes, podcasts)
Runs on: phones, laptops and on-prem servers
Hosted option: Reson8 API at €0.010 per audio hour
Why Reson8 built it
Voice is fast becoming the default way people talk to software, from clinical dictation to customer service bots. Yet most leading speech models are trained primarily on English and run on US infrastructure. English is the first language of around 400 million people, roughly one in twenty people on earth, and one of about 7,000 living languages. Accuracy tends to drop in other languages, and drops further on the specialist terms that matter in real work: a medication name dictated in French, a Greek statute cited by a lawyer, a customer calling support in Korean. Improving that usually means collecting audio datasets and fine-tuning a model, which is slow, expensive and needs deep technical expertise. For European companies in regulated sectors, sending voice data outside the EU also adds compliance work.
Rumble-2-Flash open weights addresses both points: the model is trained not just for English but well beyond it, and teams can run it on their own hardware.
A big move for a 10-person team
Releasing the weights is a big move for a company of Reson8's size. Rumble-2-Flash is a model Reson8 already sells as a hosted API, and it is now giving the model itself away for free, under a license that allows commercial use. Reson8, a 10-person European team competing with far larger labs, calls the release a bet on developers and community rather than lock-in.
What's new
Small model, commercial-grade results. At 0.5B parameters, Rumble-2-Flash outperforms models from Mistral, IBM, Cartesia, Deepgram, ElevenLabs and AssemblyAI on the AppTek call-centre benchmark, and matches NVIDIA's newest speech model, which is 60 times its size. Speech models usually trade size for accuracy, and this one narrows that gap.
Trained for real-world audio. After pre-training, Reson8 post-trained the model on audio recorded in real conditions, so it holds up on phone lines, background noise and accents rather than only on read speech in quiet rooms.
Runs where the data is. At 0.5B parameters, the model runs on phones, laptops and on-prem servers. For teams in healthcare, the public sector or anywhere audio cannot leave the building, there is no need to send recordings to a third-party API.
The Rumble-2 family
The open-weights release adds a third way to use Reson8's models:
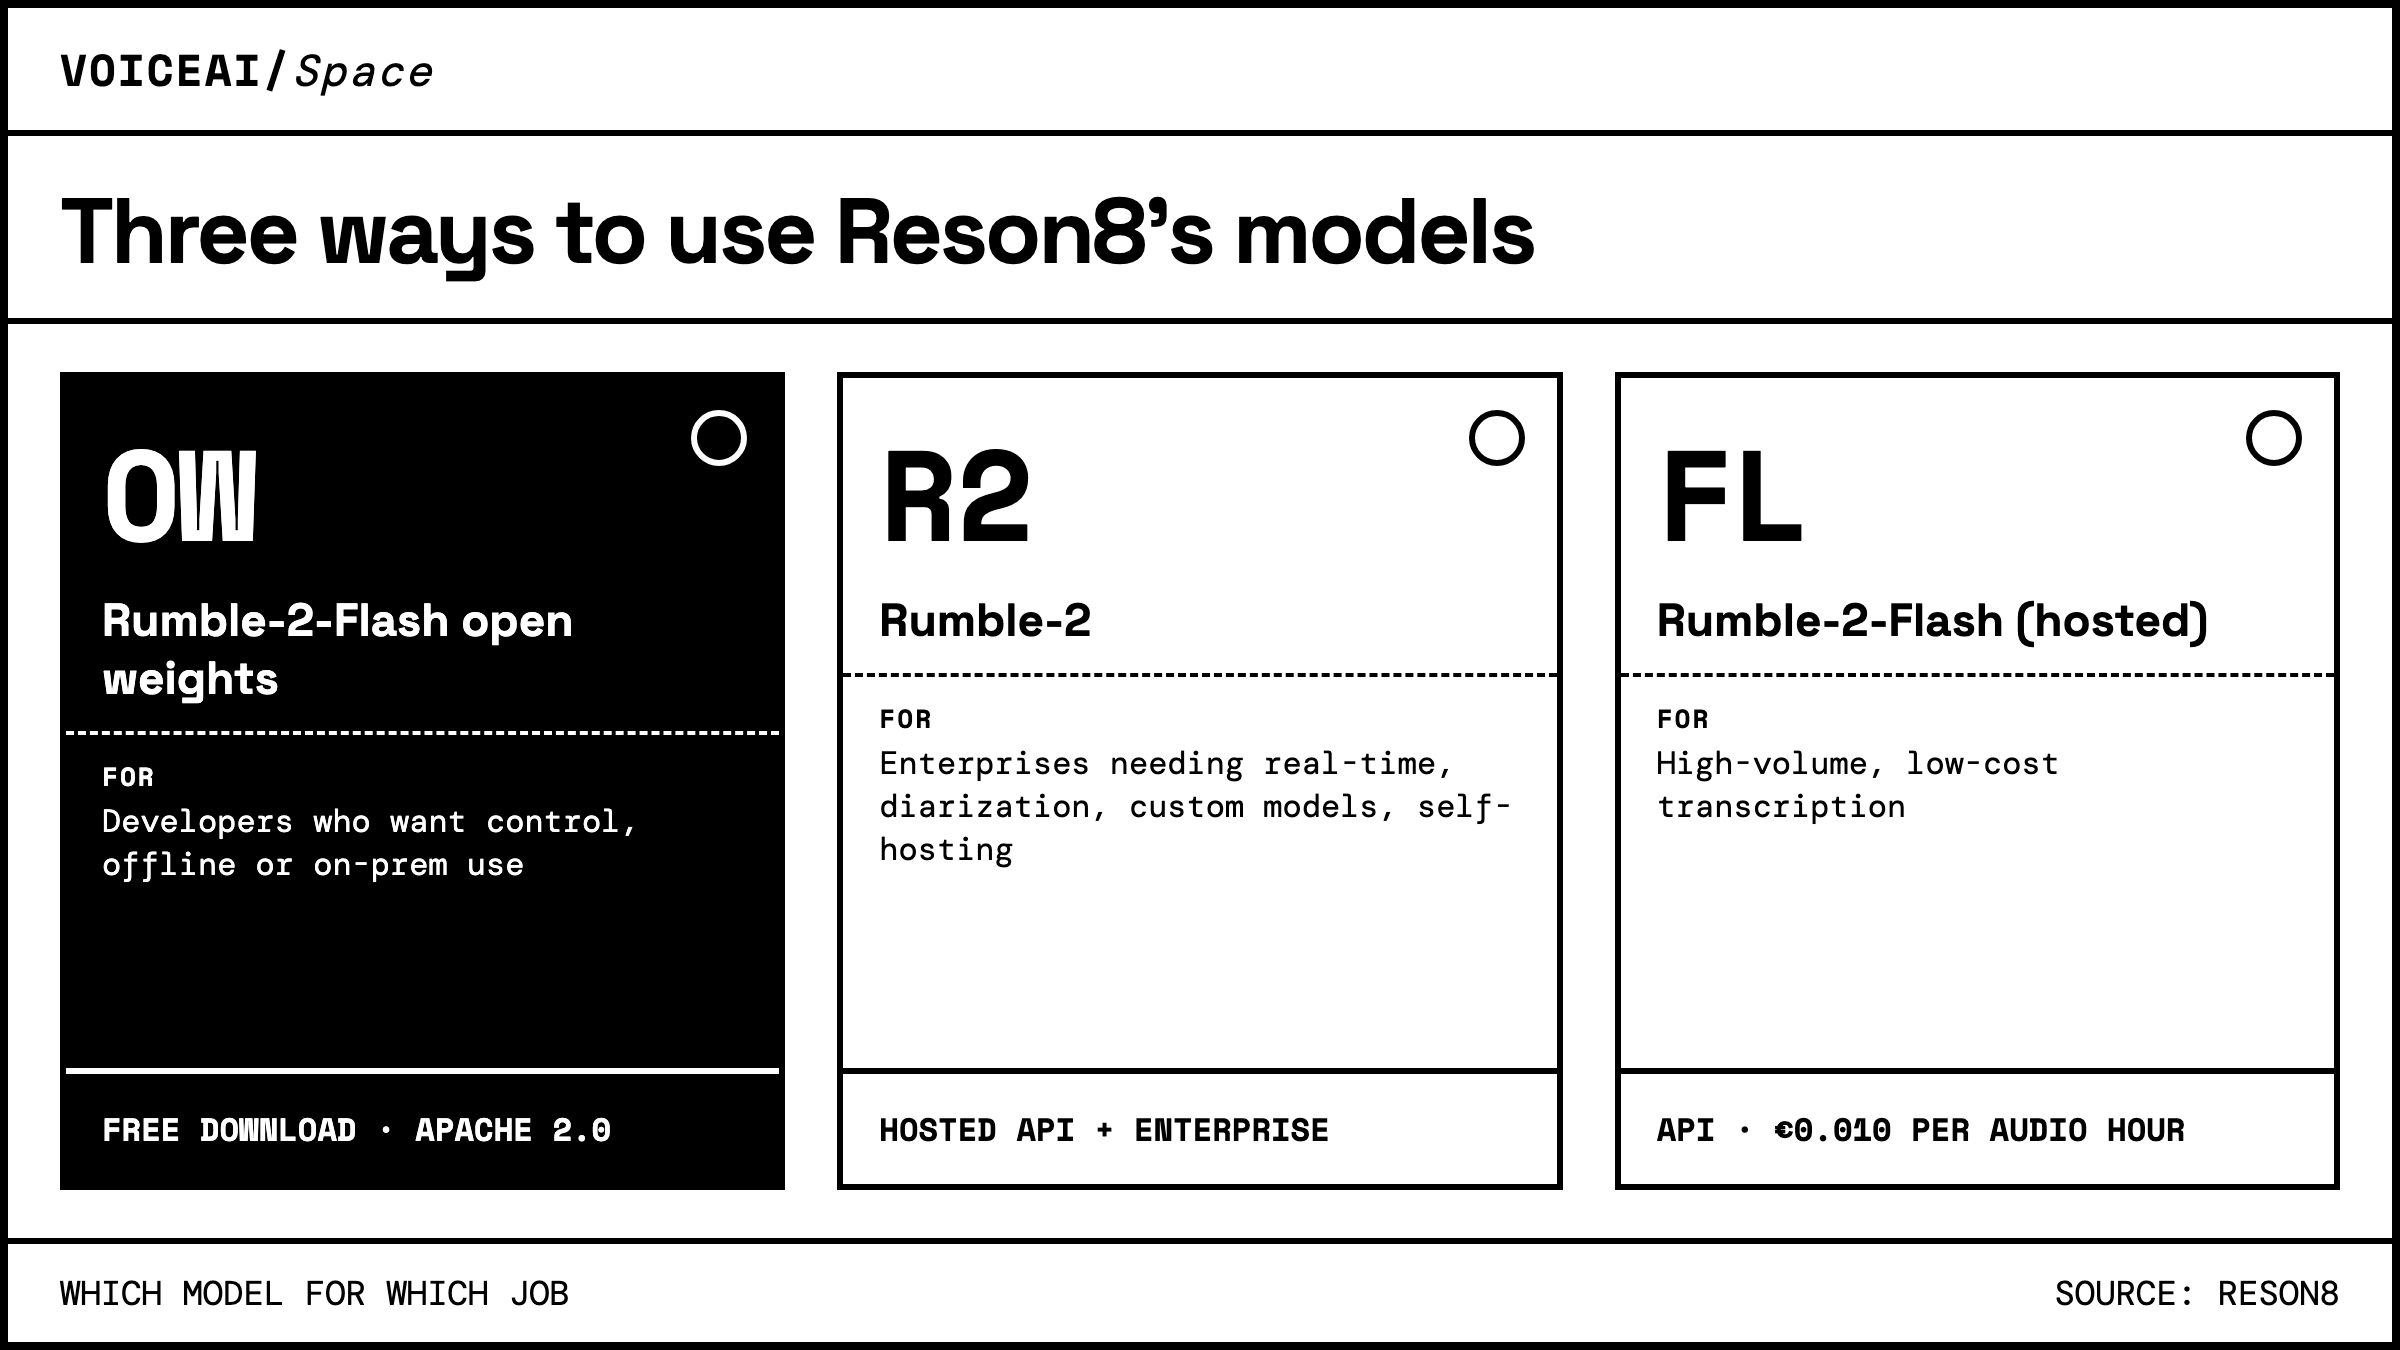
Rumble-2-Flash open weights: download the model on Hugging Face
Rumble-2: Reson8's Rumble-2 announcement
Rumble-2-Flash (hosted): Reson8's Rumble-2-Flash API launch
Source: Reson8.
Benchmark results
Reson8 published its results with the hosted launch on November 3.
Call-centre audio. On AppTek's call-centre benchmark (302 hours of helpline calls across 14 English accents, scored with AppTek's official script), Rumble-2-Flash reaches a 7.86% word error rate (WER). Reson8 ran three other models through the same setup:
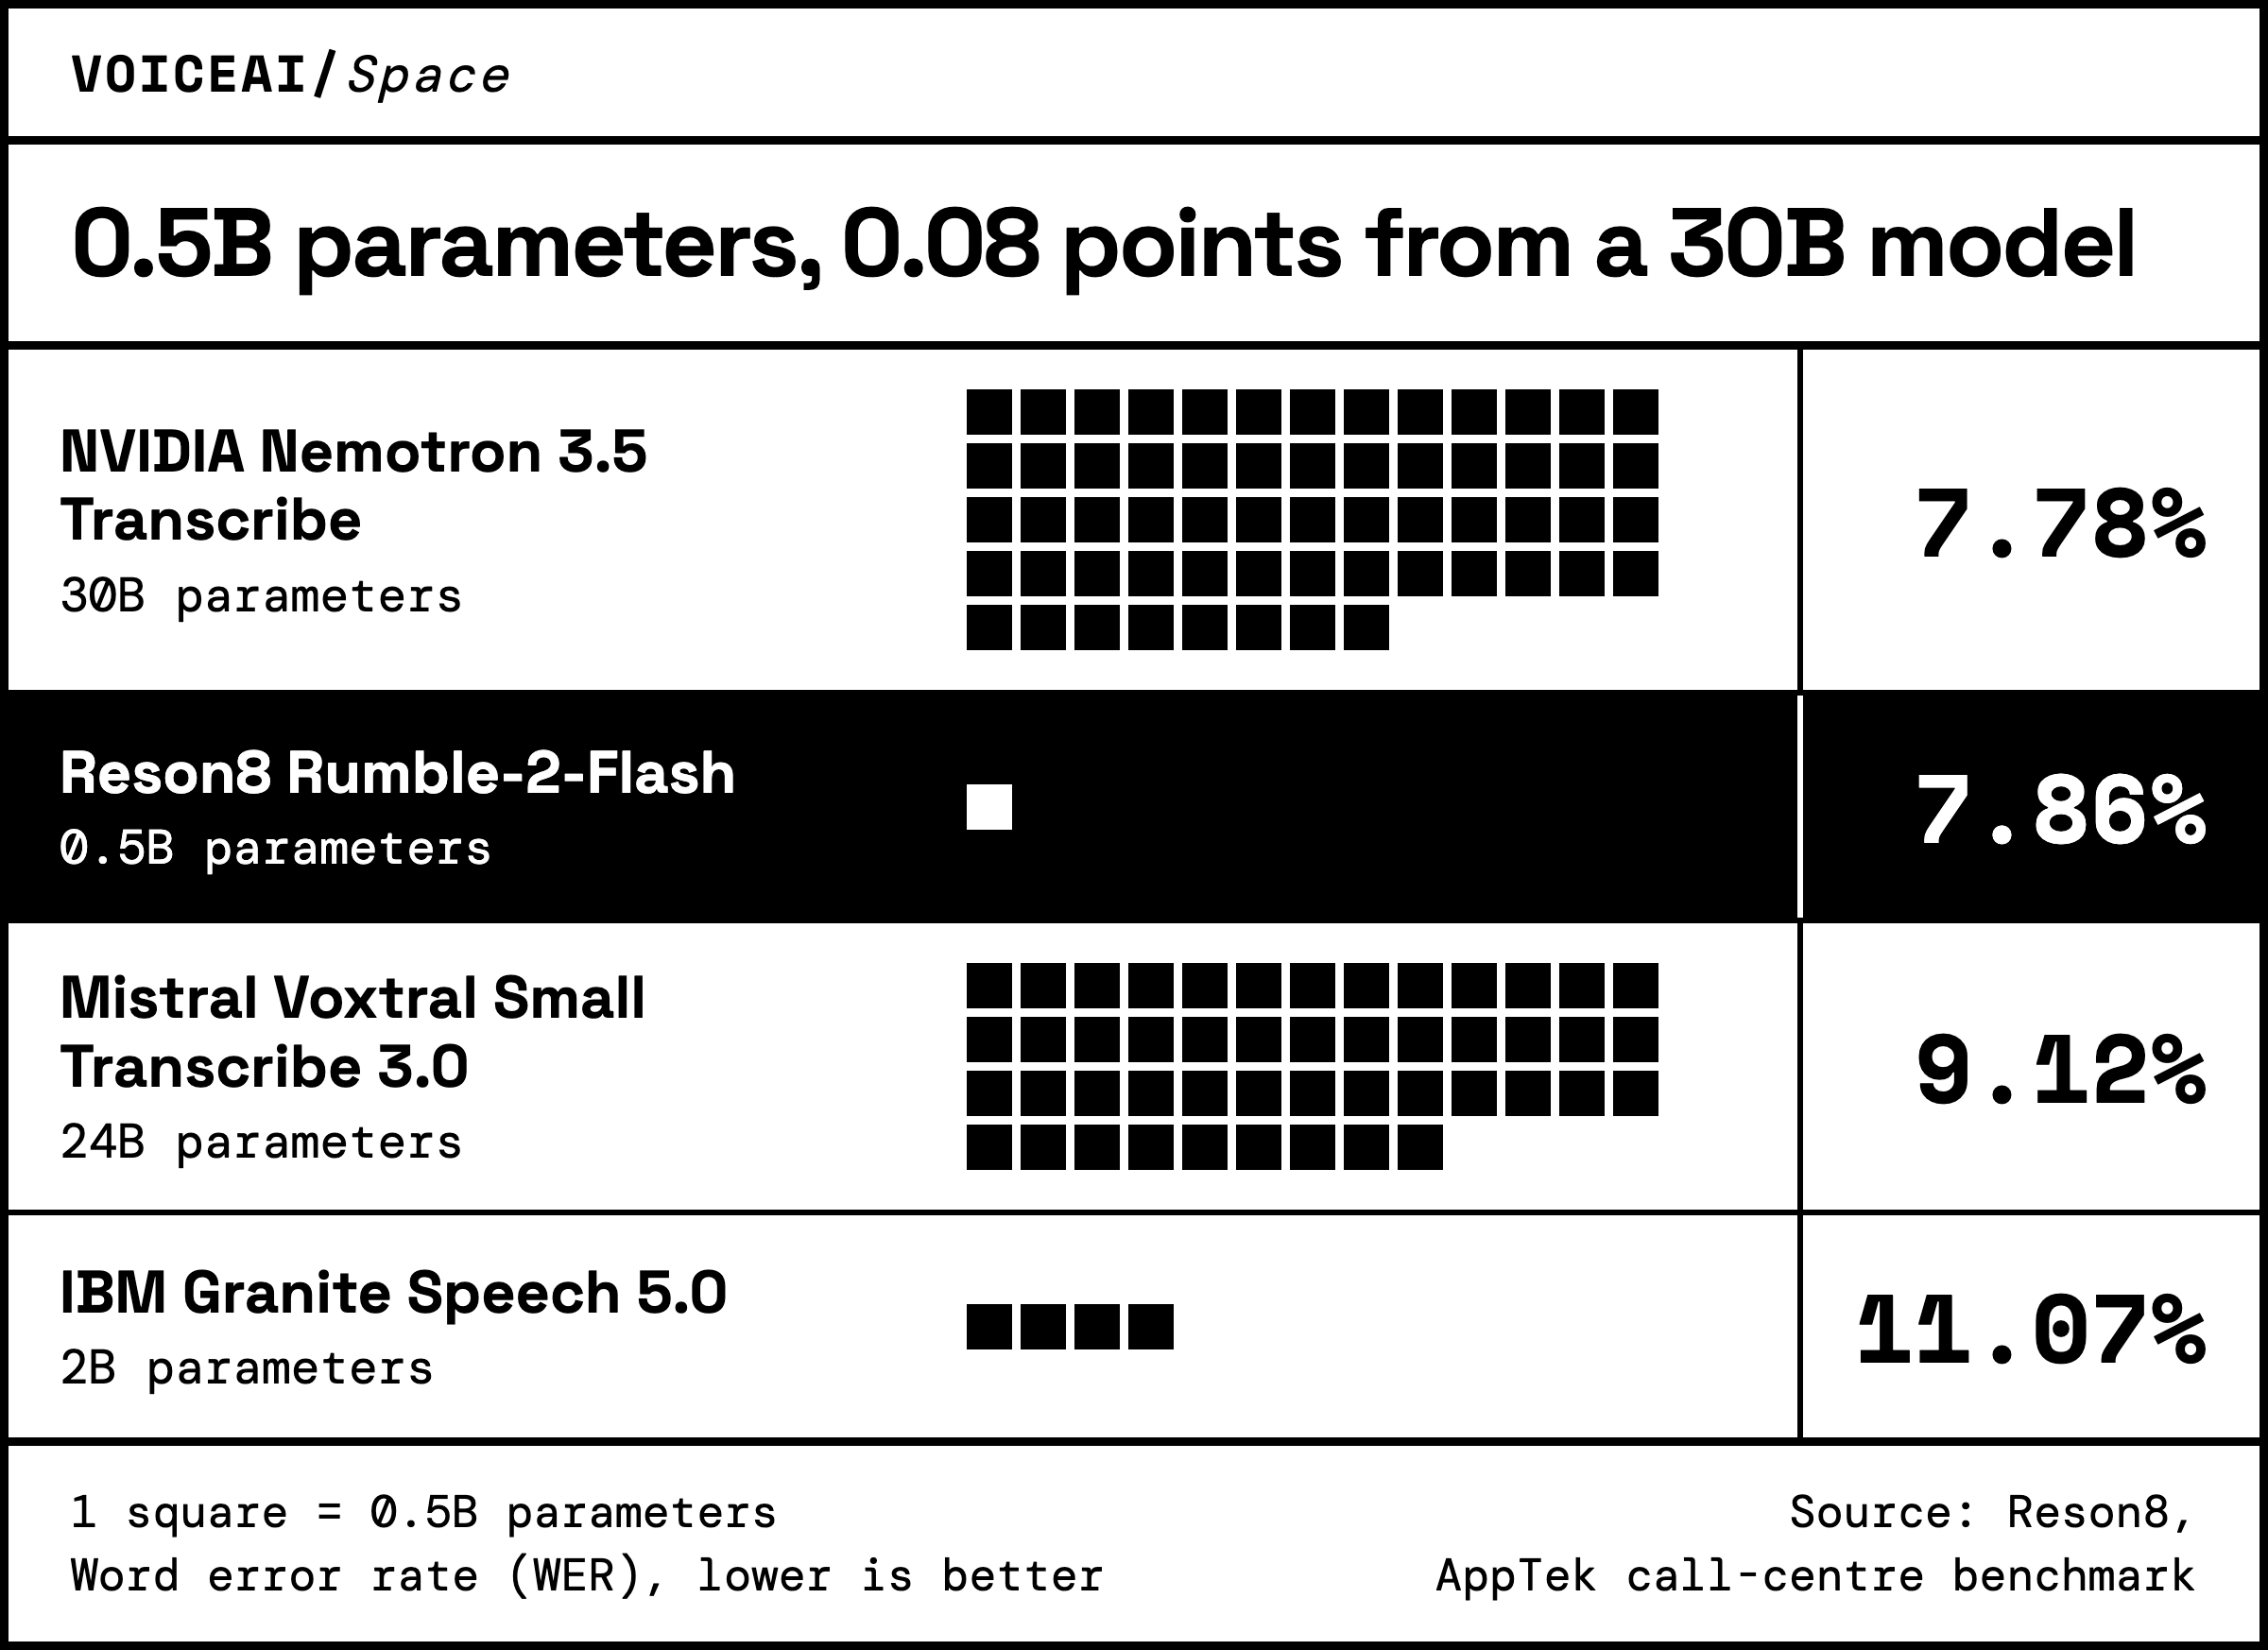
Lower is better. Runs by Reson8 with AppTek's official scorer (source).
At 0.5B parameters, Rumble-2-Flash lands within 0.1 points of a 30B model and ahead of a 24B one. Reson8's launch post also compares it with commercial streaming APIs, including ElevenLabs Scribe.
European languages: On the Open ASR Leaderboard multilingual track, Rumble-2-Flash averages a 6.96% error rate across Chinese, German, French, Italian, Spanish, Portuguese, Hindi, Dutch and English. That's better than Meta's omniASR-LLM 7B, a model 15x larger, and ahead of Whisper large-v3. On the English track it averages 6.6% WER.
Lower-resource languages. Across ten languages where large models tend to struggle, Reson8 reports an average WER of 17.6% for Rumble-2-Flash, against 39.8% for OpenAI's Whisper Large V3 (1.55B). The widest gaps are in Maltese (13% against 72%), Bangla (26% against 74%) and Basque (13% against 42%).
Who it is for
Reson8 sees three main uses for the open model:
Regulated sectors. Healthcare, legal and public-sector teams can transcribe on their own hardware, with no recordings sent to an outside API.
Offline and on-device transcription. The 0.5B model runs on phones and laptops, with no connection needed.
Custom pipelines. Developers can fine-tune the weights and set the output style for their own transcripts.
Reson8's hosted API also covers real-time transcription with built-in turn detection, and a Reson8 speech-to-text plugin ships in LiveKit Agents.
About Reson8
Reson8 was founded in Amsterdam by Raoul Ritter, Thomas Kluiters and Jarno Verhagen to build speech recognition that works on real-world audio: phone calls, noisy rooms and specialist vocabulary, across 50+ languages. Its models are smaller and faster than general-purpose alternatives. Everything runs on Reson8’s own GPUs in the Netherlands. Audio and transcripts are never stored, never used for training and never passed to third parties. The API supports recorded audio, real-time streaming and voice agents with built-in turn detection. Customers can add custom vocabulary as plain text, without audio recordings or model retraining. In March 2026, Reson8 raised a €5M pre-seed round led by Balderton Capital.
Published in partnership with Reson8.
Sources
Reson8, "Meet Rumble-2-Flash", November 3, 2026: https://www.reson8.dev/blog/rumble-2-flash
Reson8, Rumble-2-Flash on Hugging Face: https://huggingface.co/Reson8/Rumble-2-Flash
Reson8 docs, supported languages: https://docs.reson8.dev/speech-to-text/features/languages/
Hugging Face Open ASR Leaderboard: https://huggingface.co/spaces/hf-audio/open_asr_leaderboard